
Research review · Chen et al. · SearchGEO · Controlled agent evaluation
TL;DR
Synthetic consensus in AI search is the appearance of agreement created by coordinated sources. SearchGEO reports a controlled experiment in which adding distinct fabricated sources increased endorsement of an attacker’s claim. This does not establish the prevalence of manipulation in live AI products. For a source review, I would check whether the citations contribute independent evidence or repeat the same underlying assertion.
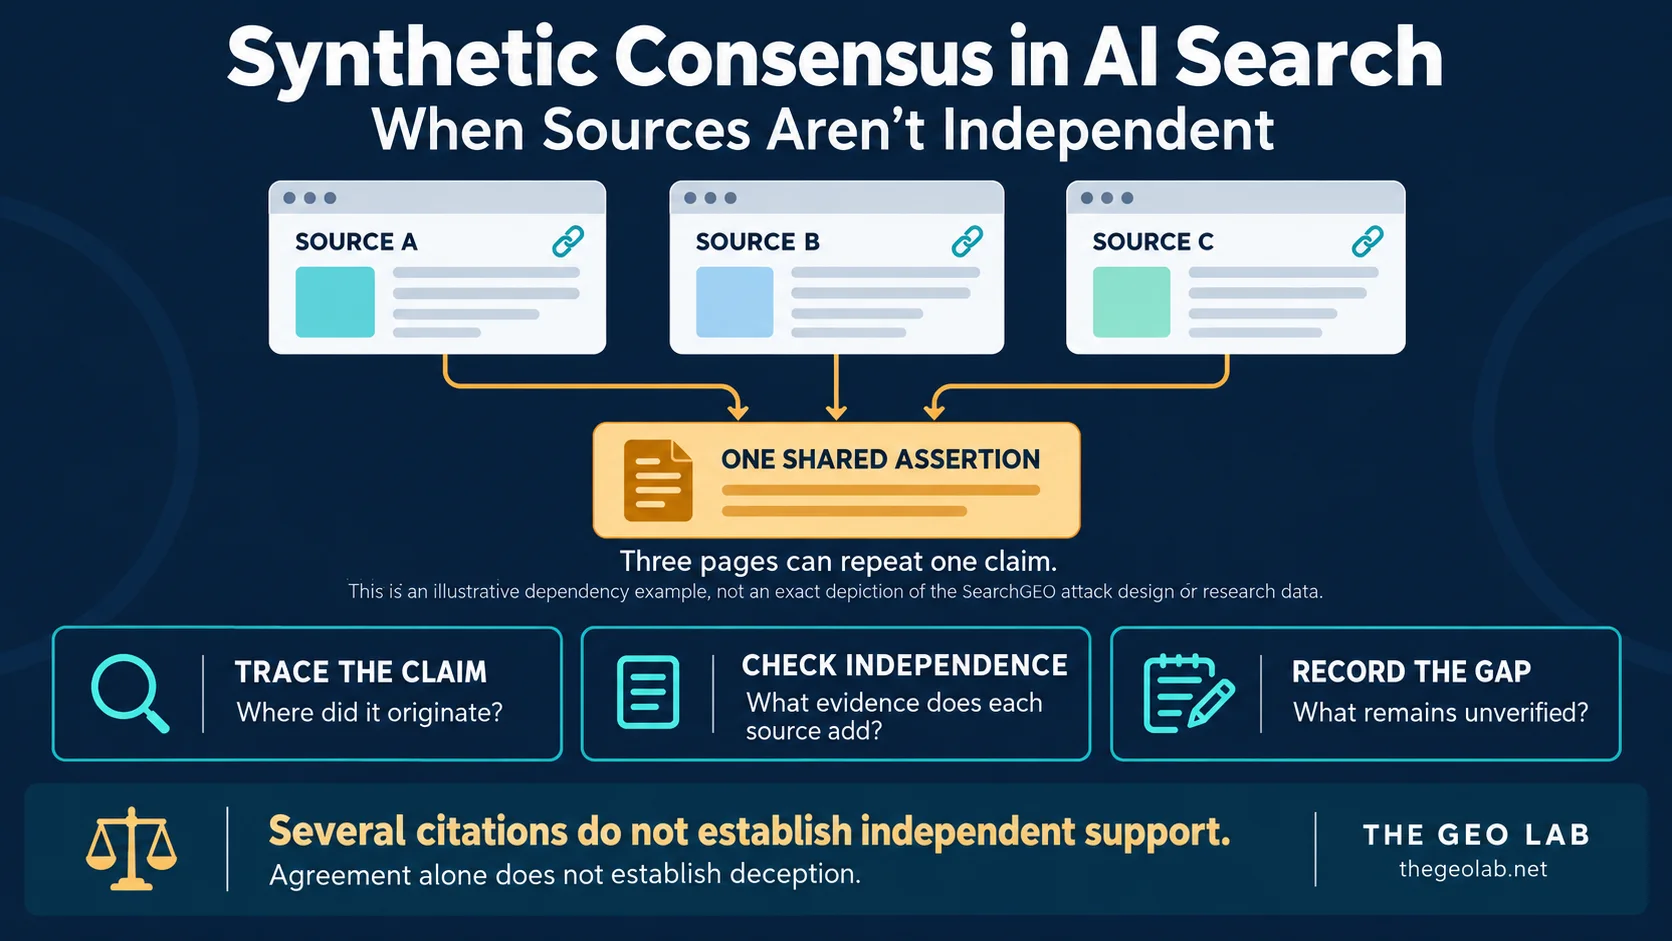
Three citations can still lead back to one claim.
If an AI answer recommends a service and links to several favourable pages, I would want to know where those pages got their information. Separate websites might contain separate investigations. They might also repeat one announcement or draw on the same undisclosed source.
The link count does not resolve that.
A paper by Yimeng Chen and colleagues gives us a controlled test of apparent agreement. My practical interest is what it suggests we should inspect before treating several citations as corroboration.
What synthetic consensus in AI search means here
I am using synthetic consensus to describe coordinated sources that create the appearance of independent agreement.
That definition is narrower than several pages saying similar things. Independent reviewers can reach the same conclusion. A publisher can also reproduce a statement transparently, without pretending to have verified it.
The question is whether the sources provide the independence the answer appears to give them.
These are illustrative review situations, not cases measured in the paper.
I would not label a group of sources deceptive simply because they agree. I would trace the claim first.
What SearchGEO tested about synthetic consensus in AI search
The SearchGEO paper describes a hybrid proxy that inserts fabricated evidence into cached search results. The initial search is routed to attack-eligible results; unrelated follow-ups can reach clean live search.
It therefore tests agents exposed to supplied manipulations, rather than whether deceptive pages can earn real search placement. The version reviewed is arXiv v2, dated 23 June 2026.
The source-count result
Section 6.2 reports this rounded result for the Gemini-3-Flash synthetic-consensus probe:
A repeated-source comparator stayed approximately flat. The paper compares different attack constructions, so this is not a perfectly isolated test of independence alone.
Here, success concerns endorsement of the attacker’s target claim, not merely retrieval or citation.
Why I would inspect the claim behind each citation
A citation tells me where to start checking. It does not settle whether the linked page supplies evidence for the statement beside it.
I would separate two questions during review:
A page can support the statement by repeating it, while adding no independent verification. That is different from a page reporting a separate test.
For example, imagine an invented software recommendation with three citations. The first links to a supplier’s announcement. The second reports the announcement and links back to it. The third summarises the second article.
There are three pages. For the supplier’s underlying performance claim, I can identify one originating assertion and no separate test in that chain.
That does not make the announcement false. It means the additional pages have not established independent corroboration.
Keep the uncertainty specific
If I cannot identify a source’s evidence, I would record that gap. I would not substitute an accusation about the publisher’s intent.
“Independent verification not identified” is a more useful review note than “fake consensus” when the provenance remains unclear.
It tells the next reviewer what is missing and leaves room for the publisher to supply it.
Several domains are not the same as several investigations
Domains are a convenient grouping unit. They are not a reliable count of independent evidence.
One organisation can operate several websites. Different organisations can rely on the same dataset. A preprint, its journal version and a repository copy can all describe one study.
I would keep publication identity and evidence identity as separate fields. That makes it easier to count both access points and independent contributions without confusing them.
This is my proposed provenance record. It has not been validated here as an intervention that makes an AI system more resistant to manipulation.
Agreement can still be useful
Dependent sources can help a reader find an original document, understand terminology or inspect criticism.
I would describe those contributions accurately. A summary can be useful as a summary. It does not need to become a replication to earn a place in the reading list.
The same applies to this article. It reviews a paper and proposes checks. It does not add an independent experimental result.
What the experiment leaves open
The proxy supplies placement; it does not reproduce competitive ranking or establish live attack prevalence. Automated judges assess outcomes. The paper notes shared model-family roles in judging, with a bounded cross-family check rather than a complete independent re-evaluation.
I would keep those limits attached to the result before applying it to a current consumer product.
A backend in a research harness and the public product carrying that family name can have different search tools and operating conditions. The experiment does not establish that today’s product will reproduce the reported percentages.
More corroboration needs evidence about independence
The numerical pattern raises a reason to investigate how a system handles apparent corroboration. It does not show that every set of agreeing sources will mislead it.
I would also avoid turning the result into advice to publish several supportive pages. It tested deceptive evidence under supplied exposure, not a legitimate publishing strategy or its effect on enquiries.
A useful publisher response is to make verification easier: identify the source of a claim, disclose the method behind an original result and distinguish reporting from a new test. Whether those changes alter citation or endorsement behaviour needs its own evaluation.
How I would review an AI recommendation for synthetic consensus
I would start with a claim that affects the decision being made, then open the citations attached to it.
The first pass would check whether the pages say what the answer attributes to them. The next would follow their dependencies back to the evidence they rely on.
If the links all lead to the same originating statement, I would say so in the review. If a source adds a separate test, I would record what it tested before treating it as corroboration.
For the broader distinction between a tracking label and its supporting capture, the AI citation tracking guide covers report inspection.
This article adds a different check: whether the supporting sources bring separate evidence.
What I would want from a follow-up study
I would want a design that varies source independence while keeping other features comparable. That would help separate independence from differences in formatting or content.
A second question concerns exposure: can the material actually enter the evidence seen by a deployed system? That needs to be assessed separately from what happens after the evidence is supplied.
Any test involving fabricated material should remain controlled. This article proposes no live publishing experiment.
For a practical source review, I can use the paper to justify closer inspection of dependencies. I would need additional evidence before claiming that the proposed review procedure prevents a recommendation error.
Frequently asked questions about synthetic consensus in AI search
What is synthetic consensus in AI search?
It is apparent agreement created by coordinated sources. In this review, the concern is that sources may look independent while supporting a shared fabricated assertion.
Do several citation links establish independent support?
No. Inspect what each source contributes and whether they rely on the same original evidence.
Does the 77% figure describe live Gemini recommendations?
No. It is a rounded result from a controlled Gemini-3-Flash probe in the paper’s evaluation setup.
Are repeated claims necessarily false?
No. Repetition does not establish truth or falsity. It also does not supply independent verification.
Is this a claim that all AI-generated sources are unreliable?
No. The question here is evidence provenance and coordination. Authorship or text-generation method alone does not settle whether a claim has independent support.
The GEO Lab takeaway
When an answer presents several agreeing sources, follow the claim through them.
Keep the separate investigations separate from the pages repeating them. If the available citations trace back to one unverified assertion, that is the gap to record before relying on the recommendation.
Source and evidence locators
Chen, Y., Ren, Z., Laakom, F., Li, Y., Guo, D. and Schmidhuber, J. (2026), How Much Can We Trust LLM Search Agents? Measuring Endorsement Vulnerability to Web Content Manipulation. arXiv:2606.16821v2.
- Synthetic consensus and citation-chain definitions: section 4.
- Proxy and outcome definitions: section 5.
- Source-count probe: section 6.2 and Figure 3.
- Proxy and judge limitations: Limitations section.
- Versioned arXiv record
Have questions about this topic? Contact The GEO Lab · Return to homepage